> For the complete documentation index, see [llms.txt](https://docs.apica.io/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://docs.apica.io/flow/rules/filter.md).
# FILTER
The Filter rule allows you to filter events that meet specific criteria. This is particularly useful when you want to control the volume of data being stored or processed. For example, if you do not want to store debug or info logs, you can create a Filter rule that drops all log lines that contain these levels.
In addition to dropping entire log lines, Filter rules can also be configured to drop specific fields within a log line. This can be useful when you only want to retain certain fields of interest.
### To Create a Filter Rule:
Open **Configure Pipeline**, click **Add Rule** under **Rules**, then select **FILTER**. Complete the shared fields and condition in [Rules](/flow/rules.md).
Select preview data before choosing **Drop Labels** or condition fields. Fields load from **Pipeline Preview**. You can also type a label manually.
The FILTER form appears in **Pipeline Configuration**. It has three sections for filtering, field removal, and event suppression.
**With filter rule:**
1. Logs can be dropped based on a condition.
2. Labels within the logs can be dropped.
3. Duplicate events can be suppressed in intervals.
The first section contains shared details and the condition builder.
Then, enter the necessary details for your Filter Rule, including a name for the rule, the group it belongs to, and any parameters needed to filter your log data.
Use **+ Add more parameters** to add conditions. Conditions can use fields like log severity level or timestamp.
### Filter Logs:
Use FILTER to remove unwanted logs from the pipeline. By default, all logs are dropped when no condition is configured. When a condition is provided, only logs matching that condition are dropped.
Click **Save** in the footer to save the rule.
#### Pipeline Preview
From the left panel, select the **Dataflow** tab under the **IN** tab. Select the desired **Namespace** and **Application**. You can change the page size if required; the default page size is **10**.
The following image shows that the rule drops messages with `status == 200`.
### Filter Fields:
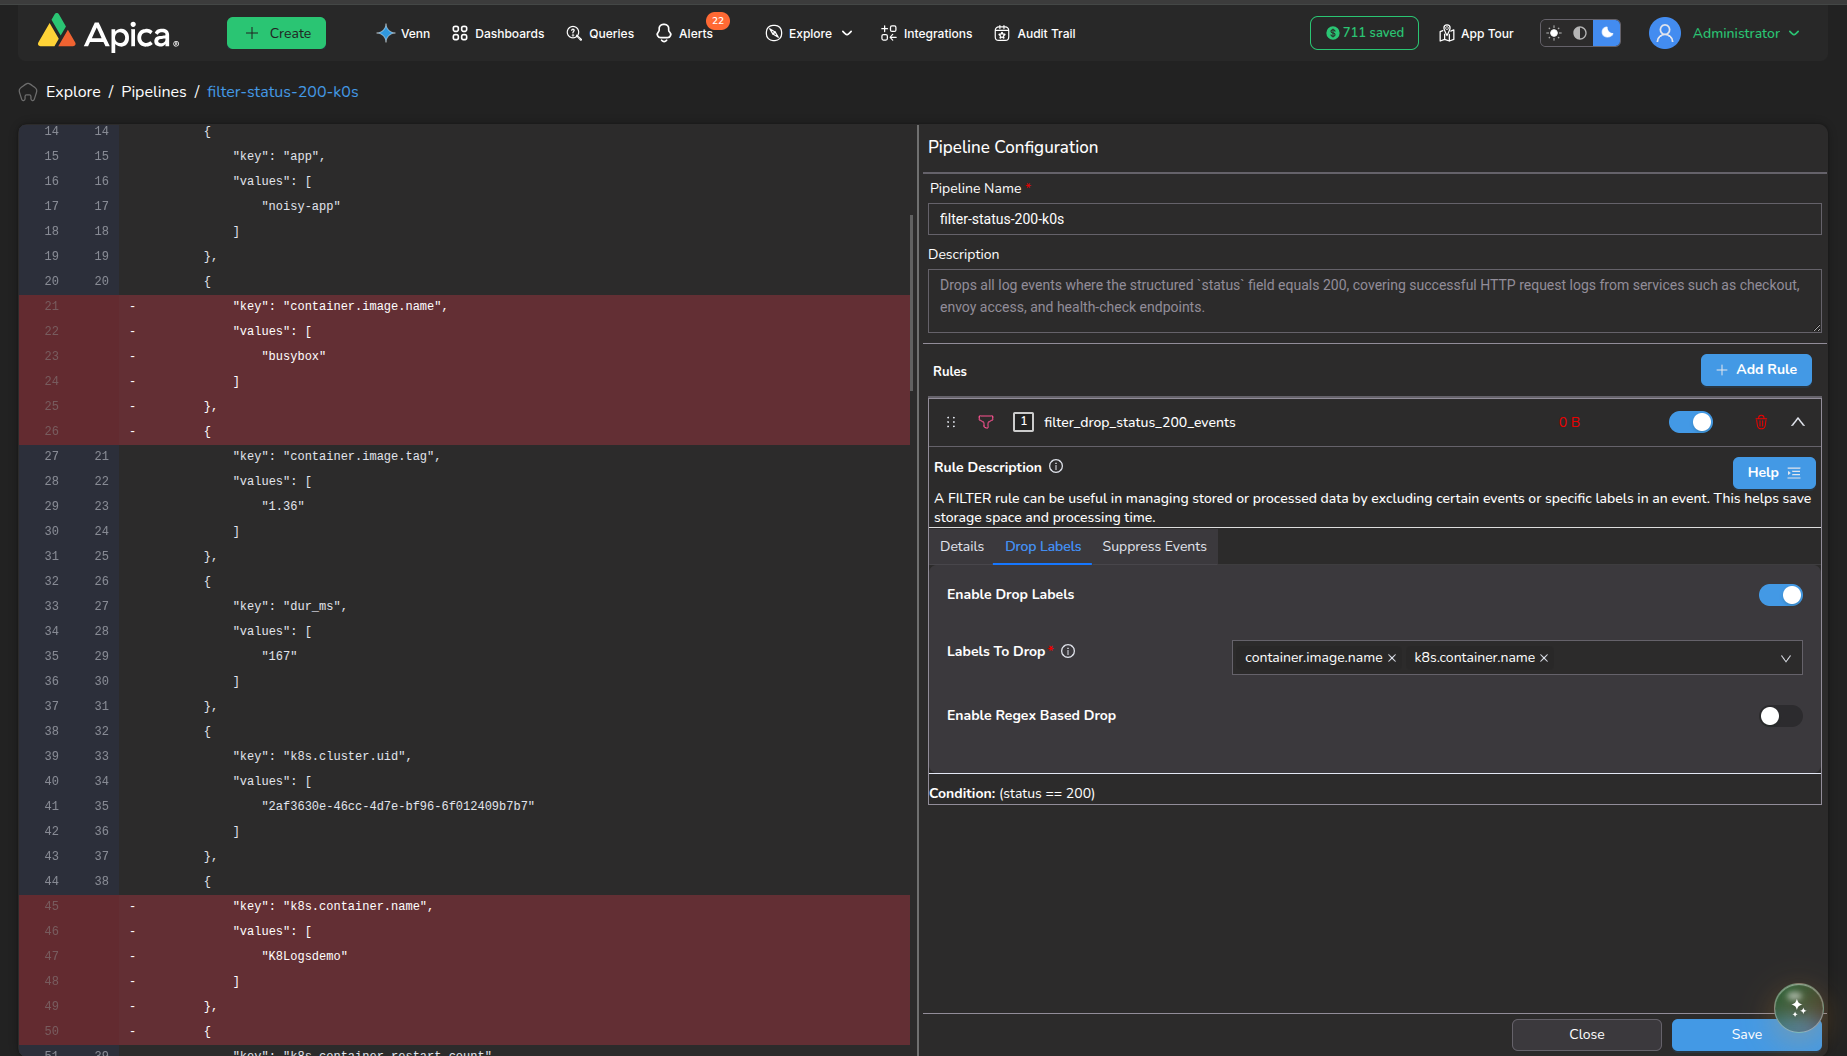
When creating a Filter Rule, users can choose to filter selected fields instead of dropping the entire log line. This can be particularly useful when logs contain metadata like Kubernetes labels that may not be needed for long-term storage or analysis.
To enable field filtering, switch over to the `Drop Labels` section and toggle the `Enable Drop Labels` . Select or enter the fields you wish to filter in the `Labels to Drop` dropdown. This will ensure that only the selected fields are dropped from the log line, while other fields will still be retained.
By using field filtering in combination with the Filter Rule, you can ensure that your log data is efficiently managed and stored, with only the necessary fields retained for further analysis.
#### Pipeline Preview - drop labels
### Suppress Events:
The filter rule can also help you drop duplicates in an interval. At the end of every interval, a certain number of logs will be allowed to flow ahead in the pipeline. To suppress events, click on the last section in the filter rule called \`Suppress Events\` and toggle `Enable Suppress Events`.
#### Pipeline Preview - suppress events
By default, the rule will drop duplicates and allow only a single log to go through. The logs that are allowed to go through will contain an extra field in the log event that is the count of suppressed logs.
Once you have created a Filter Rule and specified your filter criteria in the first tab(`Details`), all incoming log lines that match the criteria will be evaluated for de-duplication before they are sent to storage or downstream systems. This can help to control the volume of data being stored and ensure that only relevant data is retained for further analysis.
In addition to creating custom Filter Rules, Apica Ascent also offers many inbuilt Filter Rules for various applications like Java, ingress, auditd, Kubernetes, and more. These pre-built rules can be easily accessed and configured to suit your specific needs, making it easy to filter out unnecessary data from your log streams.